Sep 13, 2026
Lumi Loglake is now generally available in Imply Lumi
Search unstructured logs in place in your data lake
Learn More Julia Brouillette
In the realm of building real-time analytics applications, data teams often face a familiar challenge: the need to still retain extensive historical data, from months to even years, for occasional but valuable analytics. While the bulk of queries need to be very fast on a smaller, fresher dataset, the ability to query this older data still serves purposes such as long-term trend analysis and report generation.
In the past, Druid users would have to load all the data they ingested onto Druid’s data nodes, to ensure sub-second query performance. This meant a potentially large memory and local storage requirement to retain historical data, even if you don’t often have to query all of that data as it ages.
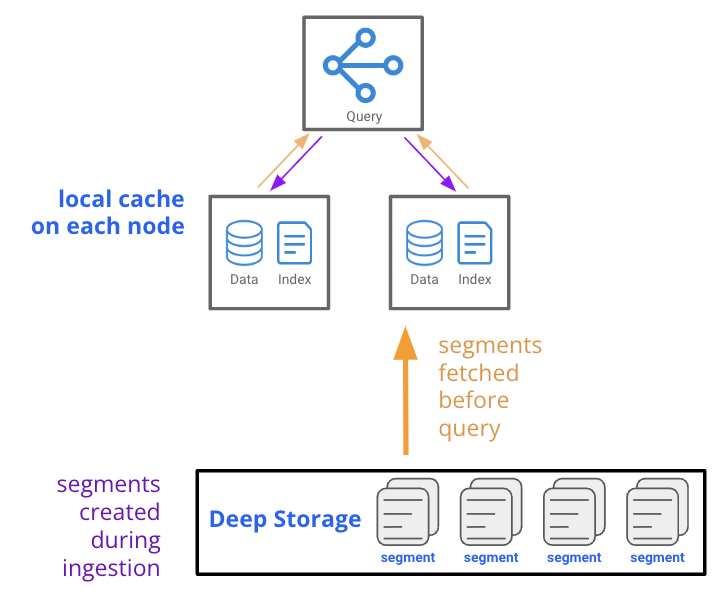
To avoid the expense of having aged data on these nodes, Druid users would often dual-load their data onto two different systems—Druid (for the fast, interactive queries) and a data lake or data warehouse (for the infrequently queried, aged data)—as the lower-performance architecture of a data lake or warehouse enabled less expensive storage for infrequent, non-performance-sensitive queries.
What’s interesting to note is that Druid has always had a deep storage layer in its architecture, as illustrated in the diagram above (figure 1). The deep storage layer wasn’t initially intended for queries—it had a different purpose. This layer is used to facilitate easy scalability and data durability. However, the use of deep storage has now expanded with the release of Druid 28.0.
Now, Druid offers a simpler, cost-effective solution with its new feature, Query from Deep Storage. This feature enables you to query Druid’s deep storage layer directly without having to preload all of your data onto Druid’s data servers. This means only fresh data (or whatever is needed for real-time queries) is kept in memory or local storage, keeping old, infrequently accessed data in deep storage. Since object storage comes with higher latency, deep storage queries can be run asynchronously, so they don’t impact the latency of real-time queries.
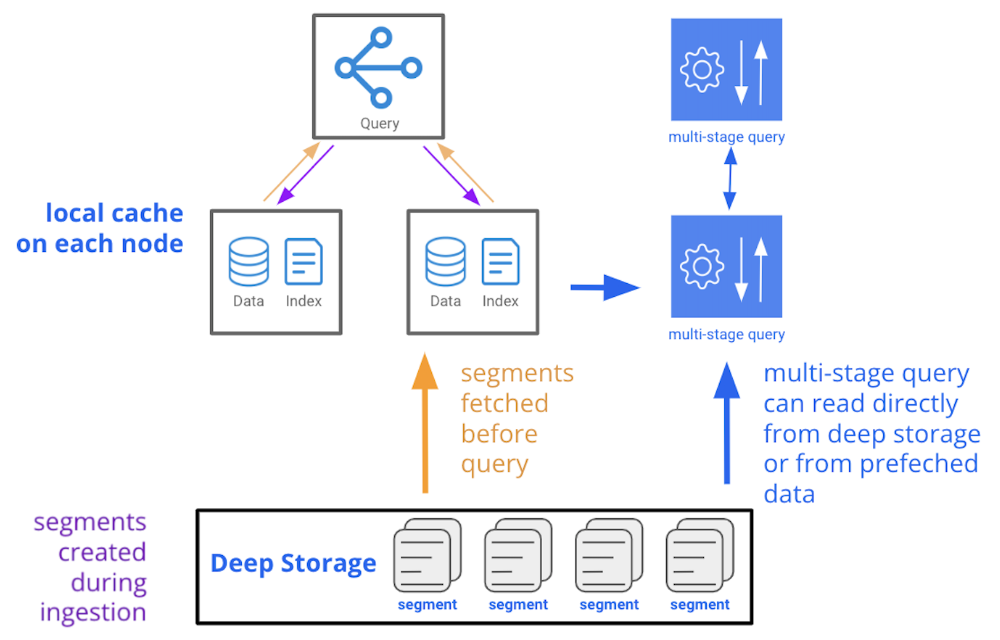
This capability represents a significant evolution in the role of deep storage within Druid, allowing organizations to keep historical and real-time data efficiently in one system while optimizing the price-performance ratio.
Druid’s Query from Deep Storage offers several key benefits:
The ability to query from deep storage (common deep storage formats are cloud object storage or HDFS) eliminates the need for high-performance storage and compute resources for infrequent access to large datasets. This makes Druid more elastic, offering users the ability to scale resources up or down based on usage while only paying for what’s being used.
Keeping all data within a single system also provides a higher level of reporting consistency. Modern data systems use approximation and statistical algorithms to ensure performance at scale. Unique values calculated in one system will be different from those calculated in another system. So in addition to simplifying data architecture, Druid’s ability to handle real-time and non-real-time workloads lends itself to more consistency in reporting.
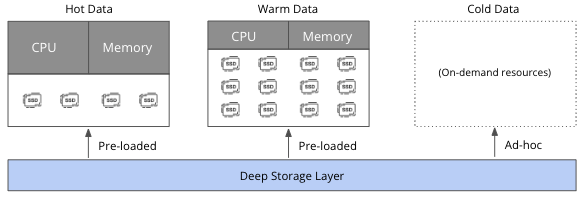
Druid’s querying from deep storage feature makes it a valuable add-on to real-time analytics applications. Let’s explore a few examples:
The ability to enable on-demand ad-hoc analysis is a powerful feature for analysts using Druid. This functionality allows users to query data beyond the retention period of the real-time Druid cluster, providing a cost-effective solution for in-depth exploration of historical data, albeit with higher latency.
In Druid deployments of the past, the amount of historical data in the cluster was limited by data storage costs. Analysts seeking to dive into historical data beyond this period would encounter limitations, necessitating workarounds like age data to a data lake for ad-hoc historical querying.
With the introduction of Druid’s Query from Deep Storage capability, users can seamlessly extend their historical analysis beyond the real-time cluster’s retention period. While this approach incurs higher latency (compared to Druid’s typical subsecond query performance) due to data retrieval from deep storage, its cost-effectiveness makes it an attractive alternative. Developers and analysts can now engage in on-demand historical analysis without workarounds, simplifying the process and making it easier to perform historical data exploration.
Druid now empowers developers to integrate export and download features into their applications, allowing users to access and download large datasets or reports generated from historical data, providing them with valuable insights and a deeper understanding of trends, patterns, and historical performance.
In the past, exporting and downloading substantial datasets or reports from Druid could be challenging. This could lead to increased resource usage as the system loads data into memory for export, impacting real-time query latency. Large export queries could time out and fail to complete.
Druid’s Query from Deep Storage capability enables the efficient and cost-effective retrieval of large datasets or reports, ensuring users experience a smoother process without the potential costs and impact on real-time performance. Now it’s easy to export data of any size, for archives, migration (such as between open source Druid and Imply Polaris, a Database-as-a-Service based on Druid), or any other reason.
Druid excels at powering real-time analytics applications, but sometimes, users need to run resource-intensive queries for in-depth reporting, such as those involving large complex joins. Recently added support for query-time Broadcast Joins and Shuffle Joins makes these complex queries possible, accommodating diverse data needs. The ability to perform large joins at both ingestion and query time provides flexibility, particularly for existing schemas and self-joins. Moreover, the introduction of Shuffle Joins at ingestion time eliminates reliance on external tools for data preparation, making the architecture simpler and more suitable for a range of real-time and non-real-time use cases.
Druid’s join capabilities, combined with Query from Deep Storage, enable seamless integration of large datasets, providing a more efficient and cost-effective solution for handling complex analytical tasks alongside real-time analytics.
With the development of Druid’s Multi-Stage Query (MSQ) engine, Druid’s historical analysis capabilities have expanded significantly with the ability to query directly from deep storage. It simplifies the data architecture by eliminating the need to sustain large amounts of local storage to accommodate ad hoc historical analysis. This expanded role for deep storage opens up new possibilities for complex queries and reporting on historical data, making deep storage not just a reliable backup but also a functional part of the total analytics system.
To summarize, deep storage in Druid serves multiple purposes:
And now,
We are on a mission to help you—developers, engineers, architects, and builders—become the new analytics heroes!
You can get in touch with Imply by contacting us through our website. We encourage you to book a demo or start a 30-day free trial of Imply Polaris, our fully managed Database-as-a-Service.
New to Druid? Check out our Developer Center, where you can learn all things Druid with articles, lessons, how-to tutorials, and design recipes.
You can also join the Druid community on Slack to keep up with the latest news and releases, chat with other Druid users, and get answers to your real-time analytics database questions.
Lumi Loglake is now generally available in Imply Lumi
Search unstructured logs in place in your data lake
Learn MoreAgents don’t query like your detections do
A security team of four has run a major SIEM since February. Nobody on the team writes SPL. Nobody opens the console or looks at the dashboards. Every question goes through an AI agent, which writes the query,...
Learn MoreWhy You Shouldn’t Have to Delete Your VPC Flow Logs
When a security incident happens, investigators almost always start with the same questions: Which systems communicated? Where did the traffic originate? What changed before the incident? Was data exfiltrated?...
Learn More